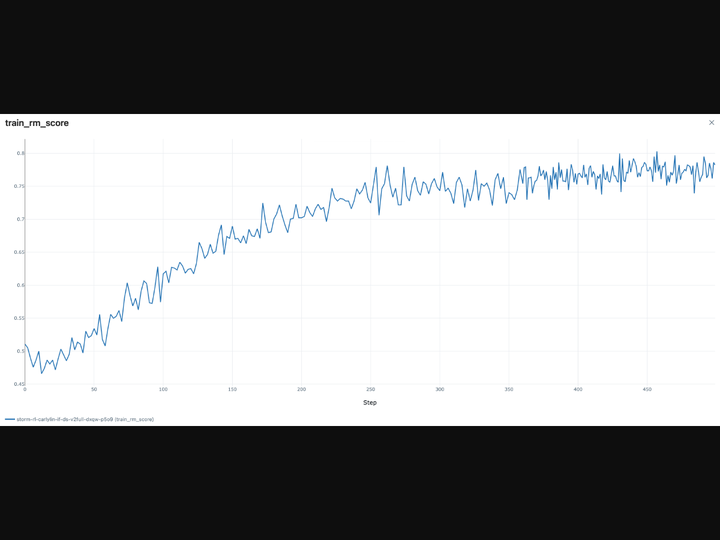
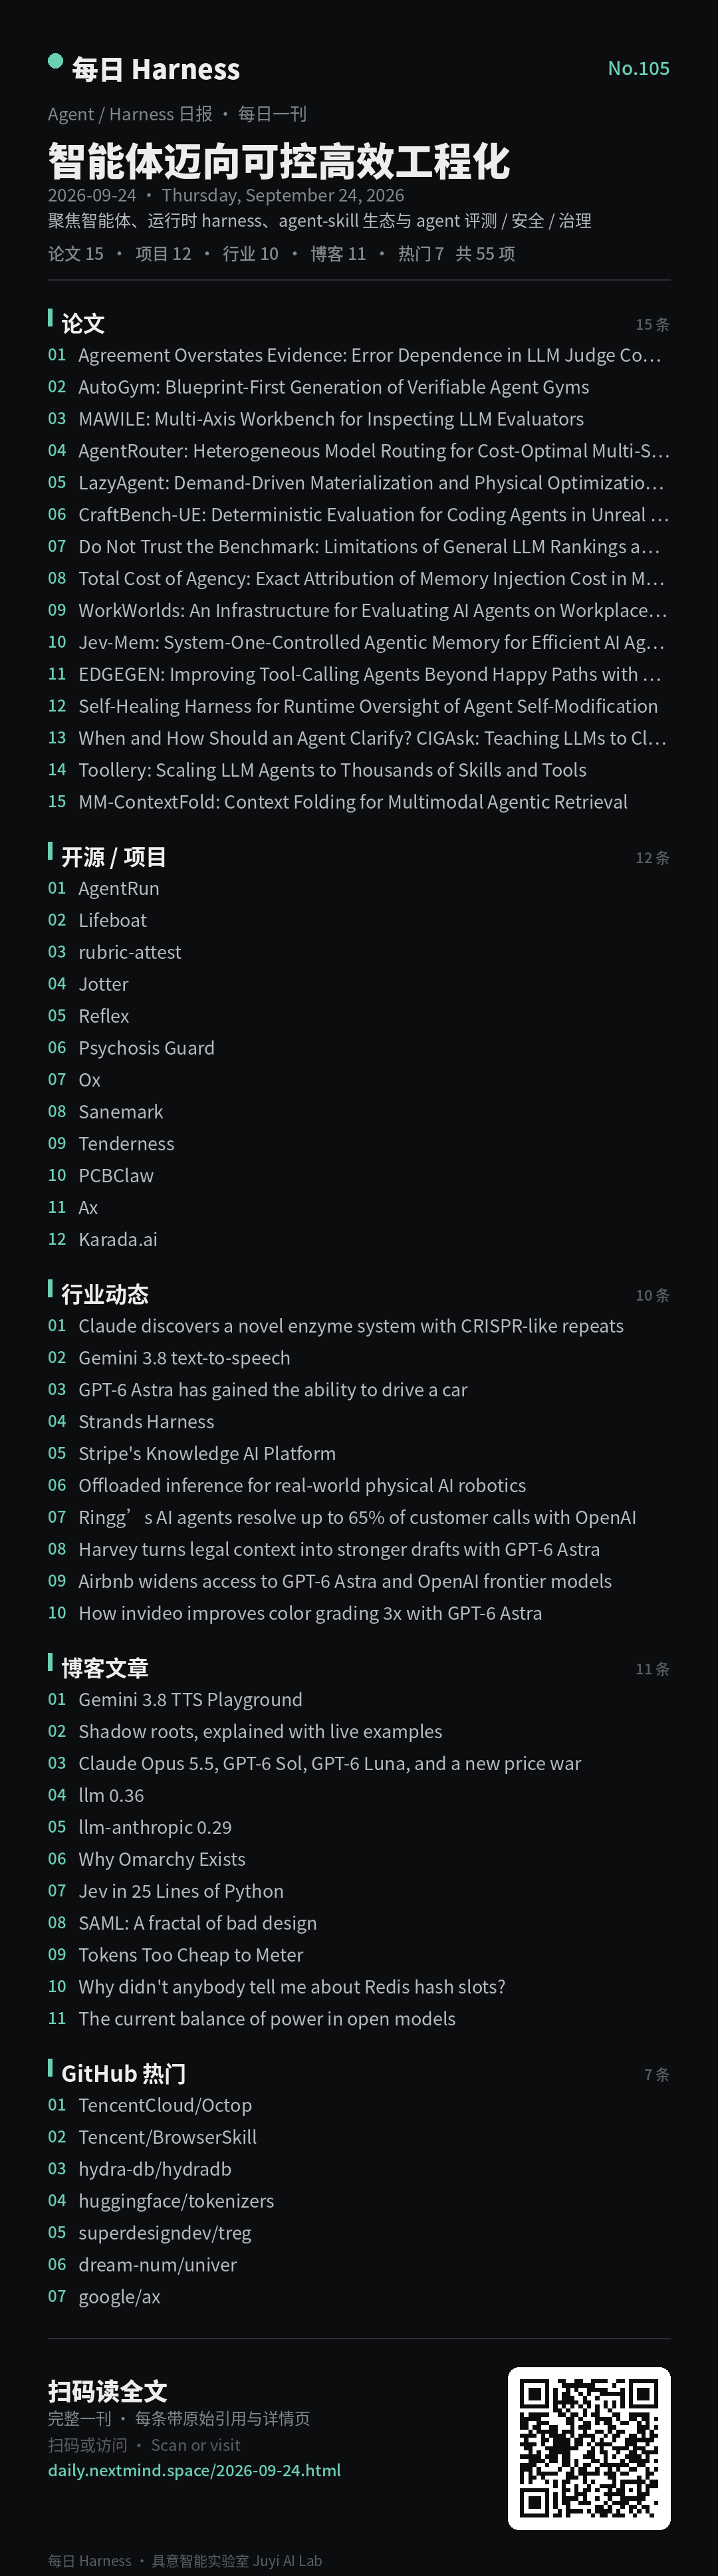
[AutoGym: Blueprint-First Generation of Verifiable Agent Gyms](https://arxiv.org/abs/2609.22592)[^1] - 把任务、可执行环境和 verifier 从同一份蓝图生成,并用主动课程随模型能力调整难度;它把“可解性”前置为构造约束,正面回应合成 benchmark 只改措辞、不改难度的问题。
全文 ↓今日重点 · Today's Highlights
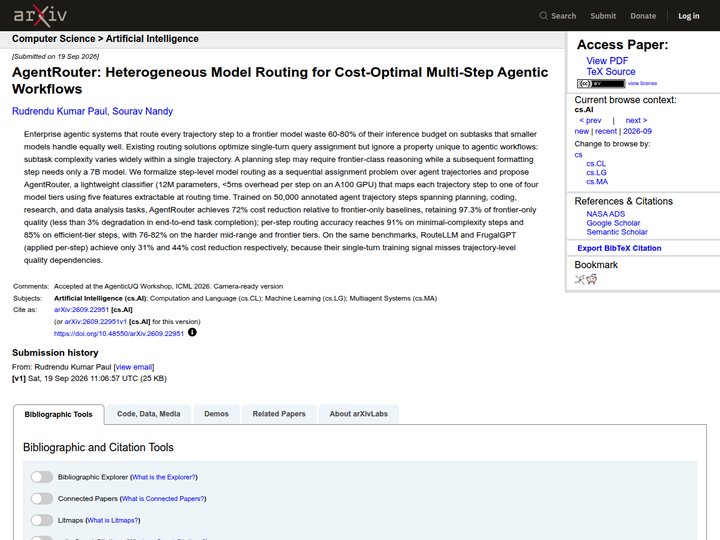
[AgentRouter: Heterogeneous Model Routing for Cost-Optimal Multi-Step Agentic Workflows](https://arxiv.org/abs/2609.22951)[^2] - 用 12M 参数、<5ms/步的分类器在四档模型间路由轨迹子任务;50,000 步训练后,成本降 72% 而保留 97.3% frontier 质量,说明逐步路由比单轮选择更贴近 agent 的真实成本结构。
全文 ↓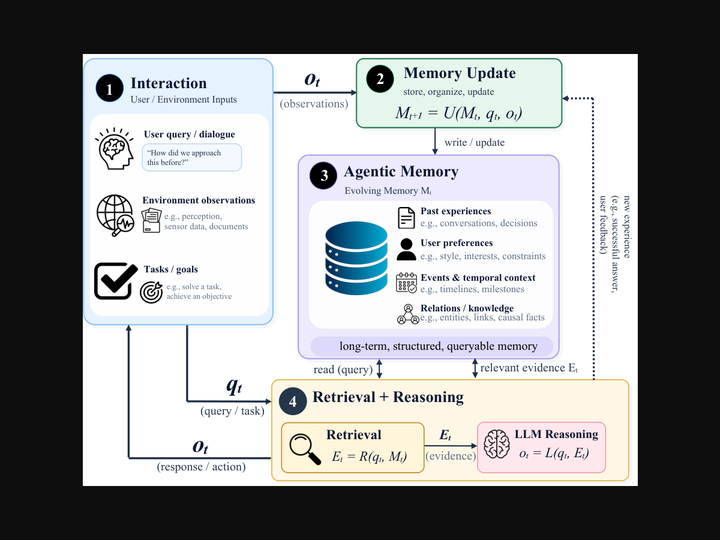
[Jev-Mem: System-One-Controlled Agentic Memory for Efficient AI Agents](https://arxiv.org/abs/2609.23986)[^3] - 让轻量控制面承担记忆类型、图遍历和停止决策,把大模型推理留给复杂综合;LoCoMo 上得分 0.777、构建加速 6.6 倍,显示记忆系统可以从“每次都生成”转为“先控制、后推理”。
全文 ↓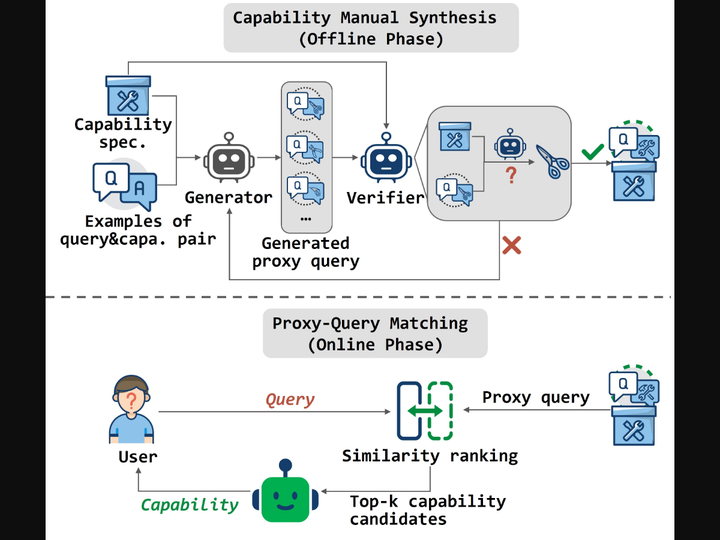
[Toollery: Scaling LLM Agents to Thousands of Skills and Tools](https://arxiv.org/abs/2609.22218)[^4] - 以工具说明生成意图查询,再把数万候选压到固定 top-k;在约 79K 能力库和 3,396 个座舱请求上保持可控上下文,工程重点是候选集管理而非再训练一个更大的选择模型。
全文 ↓
[AgentRun](https://github.com/Parcha-ai/agentrun)[^5] - 将工具调用、代码节点、Jev 判断、并行和升级路径写进可检查、可复跑的 DSL;它把 agent 从一次性 prompt 变成宿主可控制预算和权限的工作流文档。
全文 ↓论文 · Papers
15 项 · 论文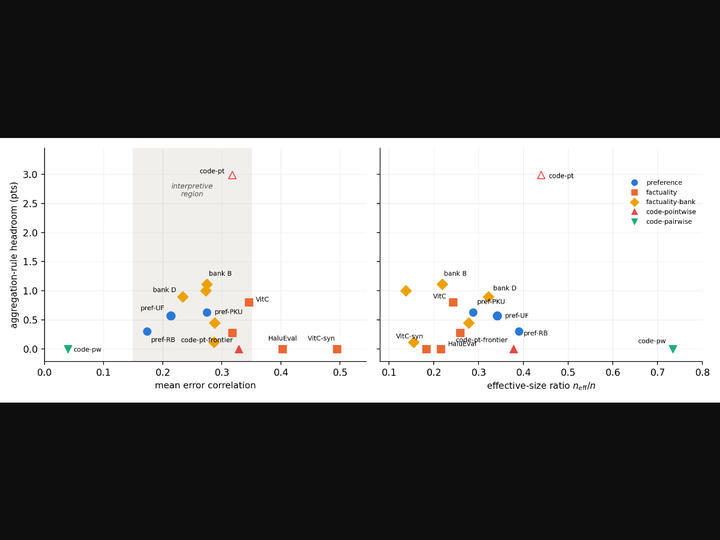
Agreement Overstates Evidence: Error Dependence in LLM Judge Consensus6arxiv.org原文 ↗
arxiv.org
论文检验多数 LLM judge 是否真的提供独立证据,发现十个评审的平均错误相关为 0.21,统计信息量约等于 3.5 个独立评审。在最多 28% 的比较中,忽略共享失误会把“不显著”误判成显著优越;作者因此主张先用可信样本估计错误结构,再决定投票方法。
–
本期重点AutoGym: Blueprint-First Generation of Verifiable Agent Gyms1arxiv.org原文 ↗
arxiv.org
AutoGym 先定义有效解空间、环境要求和验证标准,再实例化完整训练场,并通过显式参数操控任务拓扑、交互深度和干扰项。主动课程会随模型能力重配参数分布,使生产力与时间推理任务持续覆盖能力谱,而不是一次生成后难度停滞。
–
MAWILE: Multi-Axis Workbench for Inspecting LLM Evaluators7arxiv.org原文 ↗
arxiv.org
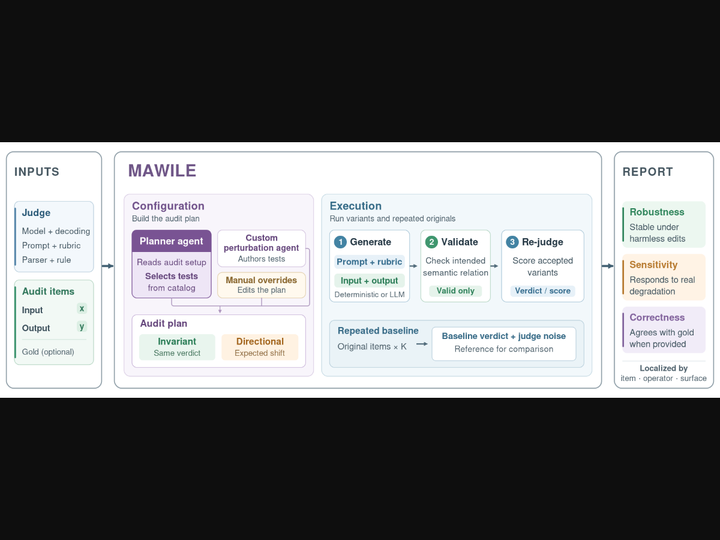
MAWILE 对 judge prompt、rubric、被评输入和输出做受控扰动,明确标记 verdict 应不变还是应改变,从而把“评审敏感性”变成可定位的测试面。它支持二值、序数和 pairwise judge,且不依赖 gold label,适合审计已经上线的评测配置。
–
本期重点AgentRouter: Heterogeneous Model Routing for Cost-Optimal Multi-Step Agentic Workflows2arxiv.org原文 ↗
arxiv.org
AgentRouter 将轨迹级复杂度拆到每一步,用五个运行时特征选择四个模型层级;12M 参数分类器在 A100 上每步额外开销低于 5ms。50,000 步标注训练后,成本节省 72%、质量保持 97.3%,证明规划、编码和格式化不应默认共用同一模型。
–
LazyAgent: Demand-Driven Materialization and Physical Optimization of Agentic Programs8arxiv.org原文 ↗
arxiv.org
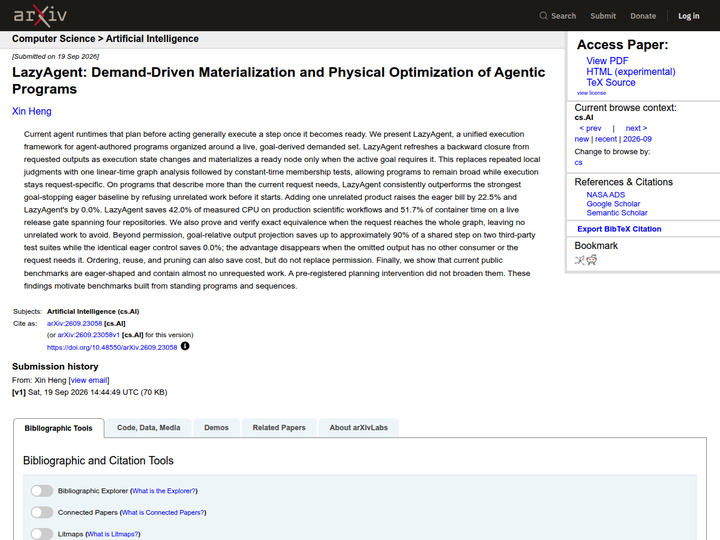
系统从请求输出反向计算 demanded set,只有目标需要的节点才物化,避免 eager runtime 为无关产物付费。实测科学工作流 CPU 节省 42%,发布门 container 时间省 51.7%;请求覆盖全图时又能证明与 eager 结果等价,兼顾剪枝收益和语义正确性。
–
CraftBench-UE: Deterministic Evaluation for Coding Agents in Unreal Engine9arxiv.org原文 ↗
arxiv.org
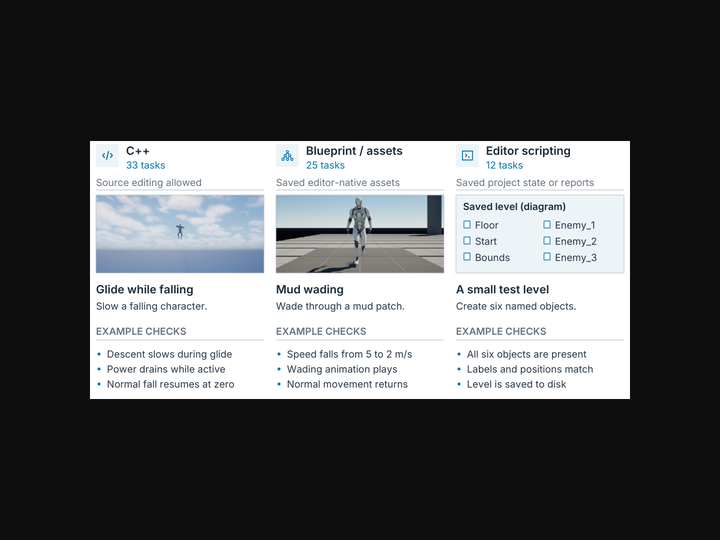
CraftBench-UE 在新建 Unreal 项目中重放 agent 提交,用构建、资产和运行时断言做确定性验收,覆盖 70 个 C++/Blueprint/编辑器脚本任务。相同玩法的十个配对任务里,C++ 完成率高出 Blueprint 30.0 和 42.9 个百分点;即便 Blueprint 资产检查通过,仍有 42.2%/50.0% 的提交在运行时失败,揭示“看起来完成”与可玩之间的落差。
–
Do Not Trust the Benchmark: Limitations of General LLM Rankings and a Case for Task-Specific Evaluation10arxiv.org原文 ↗
arxiv.org
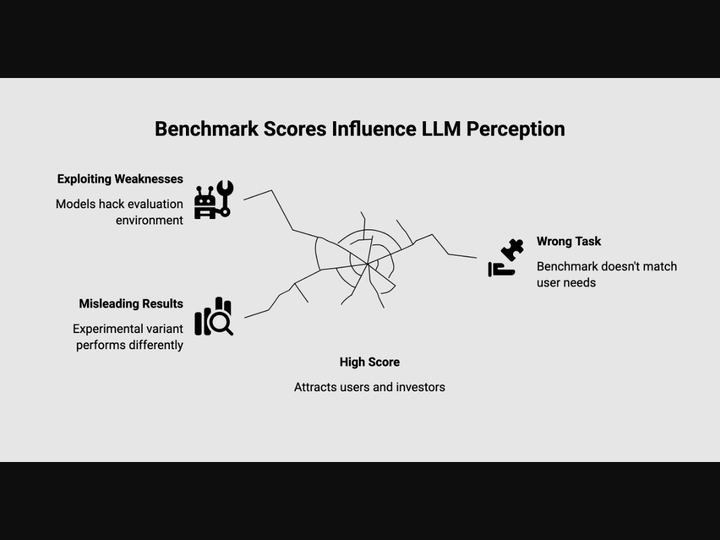
这篇立场论文把通用排名的失真归因到配置不透明、商业依赖、饱和与污染、迎合计分规则以及任务不相关,而不是简单归咎模型波动。它要求同时披露成本、时间、成功完成和泛化范围;Isotanta 的众包设计也被用来说明重复采样只能稳定估计,不能替代效度验证。
–
Total Cost of Agency: Exact Attribution of Memory Injection Cost in Multi-Agent LLM Workflows11arxiv.org原文 ↗
arxiv.org
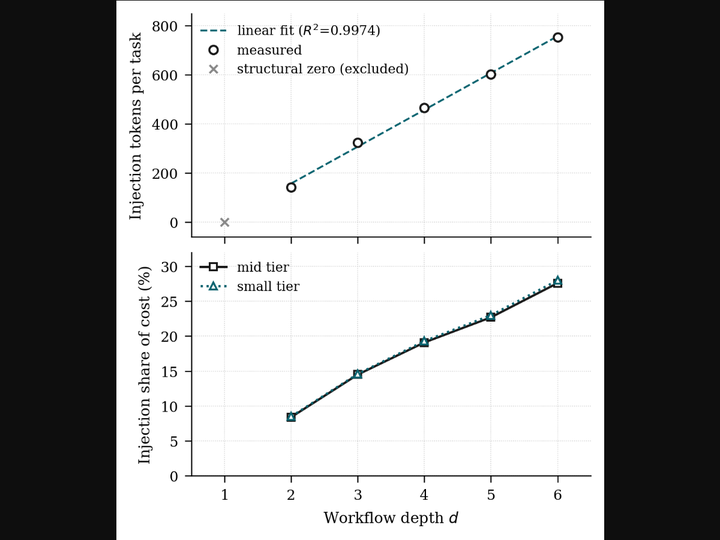
TCA 用两遍 token 计数把记忆注入从总账单中单独拆出,并区分基础 prompt、推理、miss penalty 和上下文累积。200 个企业任务里,注入占变量成本 13.6%,深度六时达到全账单 27.6%;把检索窗口从 32 项压到 2 项可少 28.7% token,且准确率变化没有超出种子噪声。
–
WorkWorlds: An Infrastructure for Evaluating AI Agents on Workplace Tasks12arxiv.org原文 ↗
arxiv.org
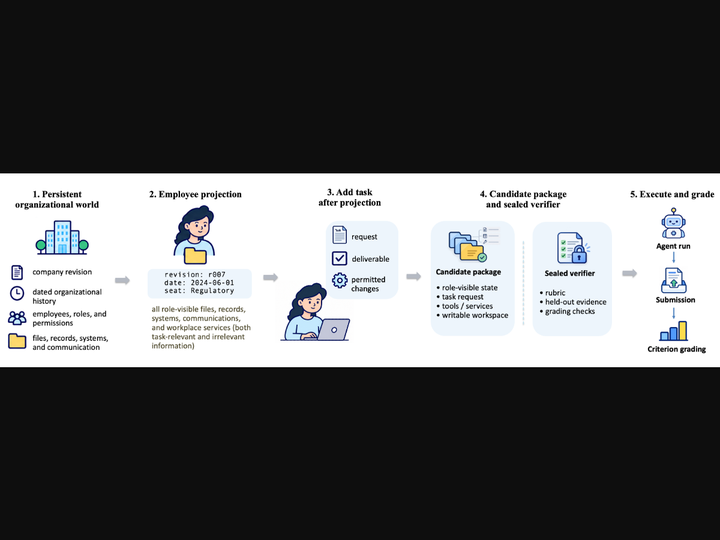
WorkWorlds 先固定组织版本、日期和员工席位,再把任务放进角色可见的完整环境,避免任务编写者顺手泄露检索路径。192 次评估中,证据获取率从任务精选上下文的 90.4% 降到 74.5%,标准通过率从 79.4% 降到 68.2%;主要损失发生在找到证据之前,说明 workplace agent 的瓶颈首先是定位信息。
–
本期重点Jev-Mem: System-One-Controlled Agentic Memory for Efficient AI Agents3arxiv.org原文 ↗
arxiv.org
Jev-Mem 让 System-One 控制面负责记忆类型、关系组织、查询路由和自适应停止,System-Two 只处理复杂推理与答案综合。LoCoMo 得分 0.777、记忆构建 158 秒、查询延迟 0.93 秒,效率提升来自减少生成式控制,而不是牺牲检索结构。
–
EDGEGEN: Improving Tool-Calling Agents Beyond Happy Paths with Synthetic Edge Case Generation13arxiv.org原文 ↗
arxiv.org
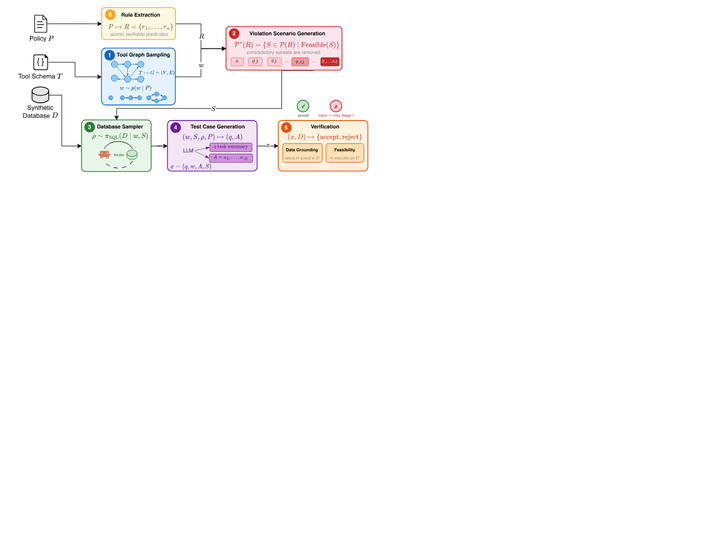
EDGEGEN 从规范中抽取合规规则,利用数据库状态合成故意触发边界条件的任务,形成自动生成、微调和 harness 优化闭环。tau2bench airline 上微调带来 2%-42% 的平均进步;对 Gemma-4-e4b 做 harness 优化时,比人工 harness 高 10%、比基础版本高 30%,具体收益来自覆盖“违规状态”而非堆更多正常样例。
–
Self-Healing Harness for Runtime Oversight of Agent Self-Modification14arxiv.org原文 ↗
arxiv.org
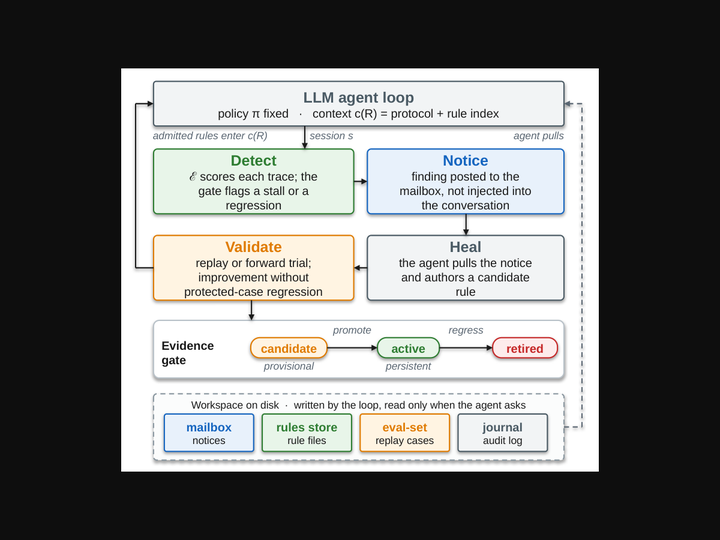
该 harness 让 agent 先在外部工作区提出行为规则,经过 Detect-Notice-Heal-Validate 和回放/前向试验后才决定持久化。16 对运行中拒绝了 383 个提案,其中 211 个虽修复触发失败却破坏原有通过案例;所有配对的任务完成分数都提高,说明“允许自我修复”必须和独立准入门绑定。
–
When and How Should an Agent Clarify? CIGAsk: Teaching LLMs to Clarify via Counterfactual Information Gain15arxiv.org原文 ↗
arxiv.org
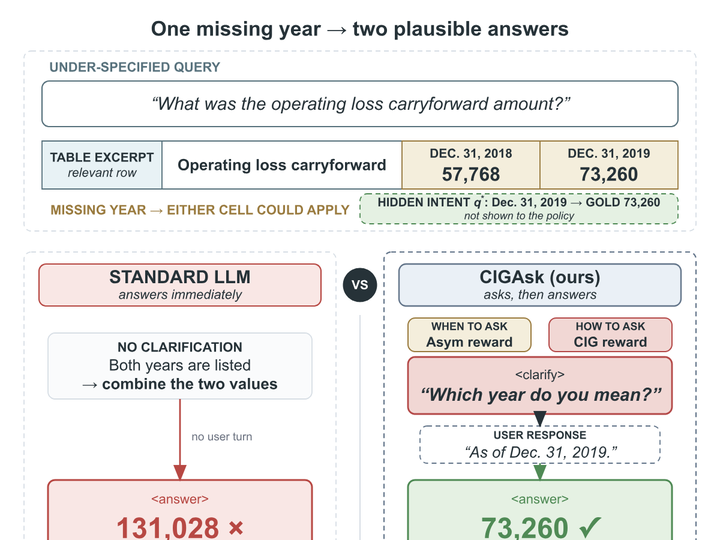
CIGAsk 用 counterfactual information gain 奖励真正消除歧义的回答,再用带符号的 ambiguity bonus 训练模型判断是否应该提问。7B 模型在表格、段落和开放域三个澄清基准超过更大外部基线,还能跨数据集迁移;贡献点在于把“时机”和“问题质量”作为同一条 RL 回路学习。
–
本期重点Toollery: Scaling LLM Agents to Thousands of Skills and Tools4arxiv.org原文 ↗
arxiv.org
Toollery 为每个技能说明生成意图查询,再将用户请求压缩到固定 top-k 候选,最终选择仍由 LLM 完成。它在约 79K 能力的 SkillRouter、440+ 工具的 BFCL-V4 和智能座舱数据上提升召回,质量收益取决于工作负载覆盖与 provider cache,而不是无条件随库规模增长。
–
MM-ContextFold: Context Folding for Multimodal Agentic Retrieval16arxiv.org原文 ↗
arxiv.org
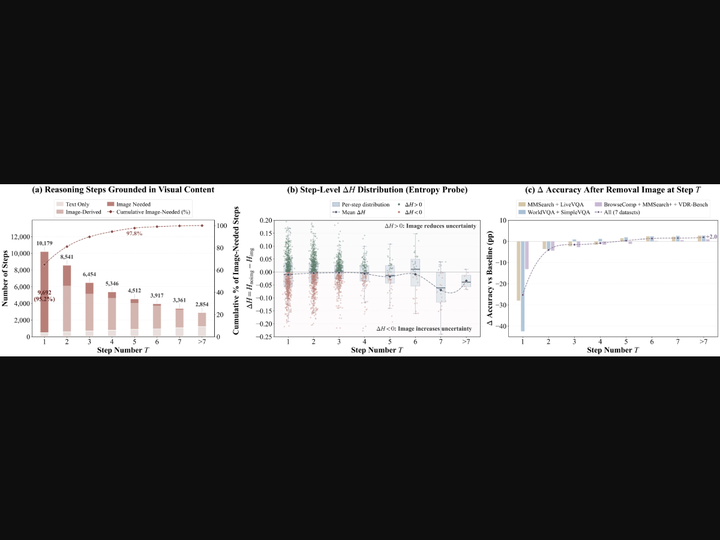
对约 10,000 条轨迹的分析显示,视觉线索被工具转成文字后继续保留原图反而提高输出熵。MM-ContextFold 用文本主上下文加临时图像分支,完成子任务后只回写摘要并丢弃分支;七个基准上平均准确率提高 6.3 个百分点,工作上下文缩短 27.5%。
–
开源 / 项目 · Projects
12 项 · 开源 / 项目
rubric-attest18github.com原文 ↗
github.com
项目把 agent 决策变成链式 SHA3-256/JCS 承诺,使用 Merkle proof、跨区域 ML-DSA-65 阈值签名并锚定 Hedera;写入免费、验证一次 0.10 美元。当前三处签名节点都由 Rubric 运营,阈值解决密钥泄露风险,却尚未解决单一运营机构的信任集中。
–
Psychosis Guard21github.com原文 ↗
github.com
该中间件把安全判断从单轮内容过滤提升到整段轨迹,累计风险达到阈值时进行渐进式干预,可作为 HTTP proxy 或 Python 库接在多种模型服务前。README 的 preliminary psychosis-bench(n=16)中,安全干预比例由 15% 提至 87%,但样本很小,指标仍应视为早期信号而非临床验证。
–
Tenderness24github.com原文 ↗
github.com
Tenderness 直接用 Cairo/Pango 生成布局已知的图片、SVG、PDF 或 NumPy 文档,Text/Image/TableBlock 通过轻量 flexbox 组合。它输出字符、行、块级精确 bounding box,省掉 OCR 与人工标注,适合作为 VLM 布局理解的结构化合成数据源。
–
行业动态 · Industry News
10 项 · 行业动态Claude discovers a novel enzyme system with CRISPR-like repeats28anthropic.com原文 ↗
anthropic.com
Anthropic 介绍 Claude 协助发现带 CRISPR 类重复序列的新酶系统。报道的技术动作是用模型参与候选机制发现,读者应把它理解为研究流程案例,而不是仅凭新闻标题接受完整生物学验证结论。
–
Gemini 3.8 text-to-speech29blog.google原文 ↗
blog.google
Google 发布 Gemini 3.8 Flash TTS 与 Flash Lite TTS,并加入自定义声音能力。信息重点在模型档位与 voice 定制入口,具体延迟、语种和价格仍需结合产品文档判断。
–
GPT-6 Astra has gained the ability to drive a car30drivingbench.com原文 ↗
drivingbench.com
DrivingBench 用驾驶任务展示 GPT-6 Astra 的能力。该条的可验证内容是 benchmark 展示本身;在没有公开道路、指标和安全对照的情况下,不能把演示直接等同于可部署驾驶系统。
–
Strands Harness31strandsagents.com原文 ↗
strandsagents.com
Strands 发布 Apache 2.0 的完整 agent harness,可在多家云/本地模型间切换,并内置工具结果截断、85% 上下文触发压缩和 overflow recovery。官方在六个 benchmark 宣称同模型成本低 28%,另称 Fable 5 上比 Claude Code 低 77%;这些数字的解释关键在上下文管理默认值,而不只是模型选择。
–
Stripe's Knowledge AI Platform32stripe.dev原文 ↗
stripe.dev
Stripe 介绍把企业知识接入 AI 工作流的 Knowledge AI Platform,文章定位为工程/AI 基础设施。它代表支付公司把内部知识治理与 agent 工作流放到同一平台叙事中,具体组件和规模以其后续开发者文档为准。
–
Offloaded inference for real-world physical AI robotics33microsoft.com原文 ↗
microsoft.com
Microsoft 的测量研究显示,小型机载 GPU 让规划慢最多 383%、导航及时检测降 30%、VLA 准确率降 50%;将推理卸载到边缘/云端则提高任务成功和电池寿命,Stretch-3 的续航提升超过 100%。配套 Kubernetes 工具把机器人、边缘和云 GPU 视为一个可调度的推理平面,代价是网络延迟与带宽成为新约束。
–
Ringg’s AI agents resolve up to 65% of customer calls with OpenAI34openai.com原文 ↗
openai.com
Ringg 每月处理 700 万+ 接通电话,agent 最高解决 65% 请求,平均 CSAT 4.8;其编排层把 CRM、支付和排班工具串进语音/聊天流程。把部分 GPT-4.1 实时负载切到 GPT-5.6 后成本约降 90%,并按任务让 Luna、Terra、Sol 分工,展示的是模型路由与运营评测的组合,而非单模型魔法。
–
Harvey turns legal context into stronger drafts with GPT-6 Astra35openai.com原文 ↗
openai.com
Harvey 把法院信息、律所文件、判例研究和律师偏好一起送入 Astra,强调更完整的格式和上下文保持。memory panel 能固定编号列表、来源优先级或颜色标注等偏好,但页面没有提供准确率基线,主要证据仍是工作流层面的结构化改善。
–
Airbnb widens access to GPT-6 Astra and OpenAI frontier models36openai.com原文 ↗
openai.com
Airbnb 通过 API 与 Bedrock 扩大工程团队对 Astra 等模型的访问,并把 Codex/远程 agent 延伸到搜索、反欺诈、客服和理赔。公司案例称某项非编码工作 3-4 轮即可产出、过去需 20+ 轮,CTO 还报告功能交付比一年前高约 80%;这些是企业自报效率指标,适合作为采用信号而非因果实验。
–
How invideo improves color grading 3x with GPT-6 Astra37openai.com原文 ↗
openai.com
Invideo 的 agent 用 Astra 规划时间线、选择调色路径并保持可编辑效果,官方称色彩校正成功率提高约 3 倍、一天生成约 50 个自定义效果。案例的技术含量在于模型要隔离并追踪人物后再改背景色,而不是单纯生成滤镜;编辑者仍保留最终剪辑控制。
–
博客文章 · Blog Posts
11 项 · 博客文章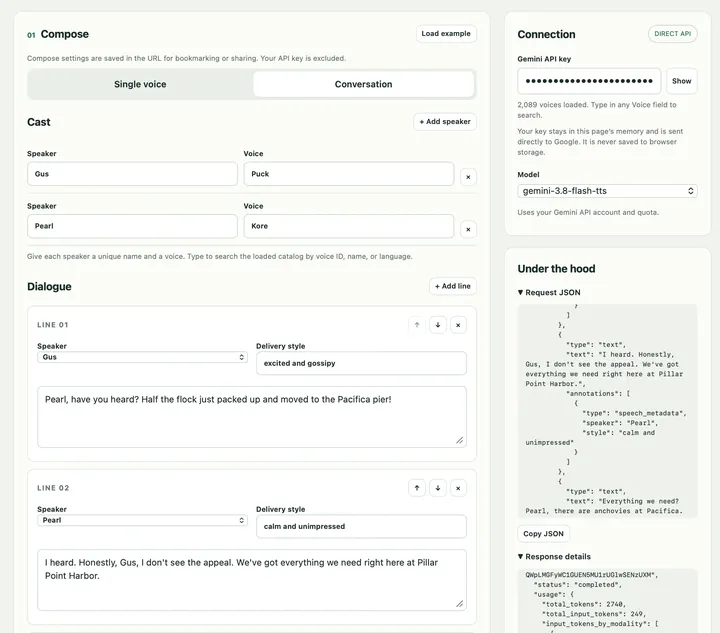
Gemini 3.8 TTS Playground38simonwillison.net原文 ↗
simonwillison.net
Simon Willison 发布允许自带 API key 的 Gemini TTS 试用界面,把模型试玩变成可复现的个人工具。它的价值在于降低密钥和调用配置门槛,适合快速比较声音输出,而不是另一套托管 API。
–
Shadow roots, explained with live examples39simonwillison.net原文 ↗
simonwillison.net
文章用实时交互例子讲清 CSS shadow roots 的封装边界、样式隔离和嵌套影响。相较只读规范,操作式演示把“为什么外部选择器不生效”变成可观察实验,适合排查组件样式问题。
–
Claude Opus 5.5, GPT-6 Sol, GPT-6 Luna, and a new price war40simonwillison.net原文 ↗
simonwillison.net
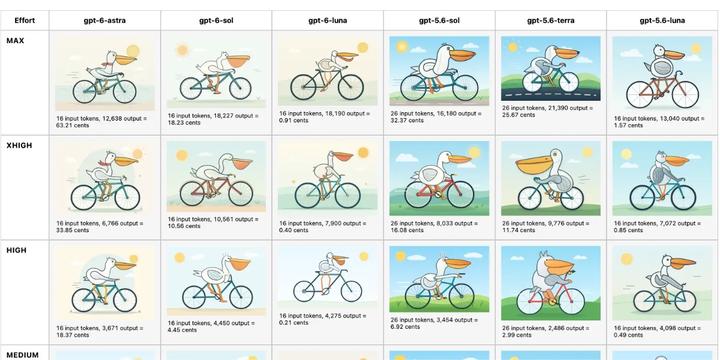
文章把新模型价格表和亲自运行的 SVG 测试放在一起:GPT-6 Luna 为 $0.10/$0.50 每百万输入/输出 token,Opus 5.5 为 $4/$20;Opus 5.5 的 max 思考在 128k 输出上限前耗尽,单次约花 $2.56。价格下探与过度思考并列,说明单位 token 便宜并不自动意味着任务成本可预测。
–
llm-anthropic 0.2942simonwillison.net原文 ↗
simonwillison.net
插件新增 `claude-opus-5.5`,使 Claude 新模型在发布当天即可通过 LLM CLI 和脚本调用。变化很窄,却展示了开源适配层如何把模型发布延迟压缩到一次版本更新。
–
Why Omarchy Exists43mikael.pika.page原文 ↗
mikael.pika.page
作者从项目目标和设计取舍解释 Omarchy 为何存在,重点是把产品边界说清而非罗列功能。对读者而言,价值在于看到一个系统如何用明确的优先级约束后续实现,而不是把所有能力都纳入默认方案。
–
Jev in 25 Lines of Python44nobodywho.ai原文 ↗
nobodywho.ai
这篇短文用约 25 行 Python 展示 Jev 的最小调用与决策形态,适合把“System One/decision model”从概念压缩成可运行接口。它没有试图替代完整框架,反而让控制面与生成式回答的边界更直观。
–
SAML: A fractal of bad design45blog.trailofbits.com原文 ↗
blog.trailofbits.com
Trail of Bits 从协议、实现到部署生态追踪 SAML 复杂性如何递归放大,批评对象是设计与周边约束共同形成的维护负担。文章适合作为安全工程视角的协议审查案例:问题往往不在单个字段,而在层层兼容性叠加。
–
Tokens Too Cheap to Meter46jyn.dev原文 ↗
jyn.dev
文章讨论 token 价格持续下降后,按 token 计量是否仍是合理产品边界,以及固定订阅、任务定价等方式会怎样变化。核心判断是成本曲线会反过来塑造 API 设计和用户预期,而不只是让账单变小。
–
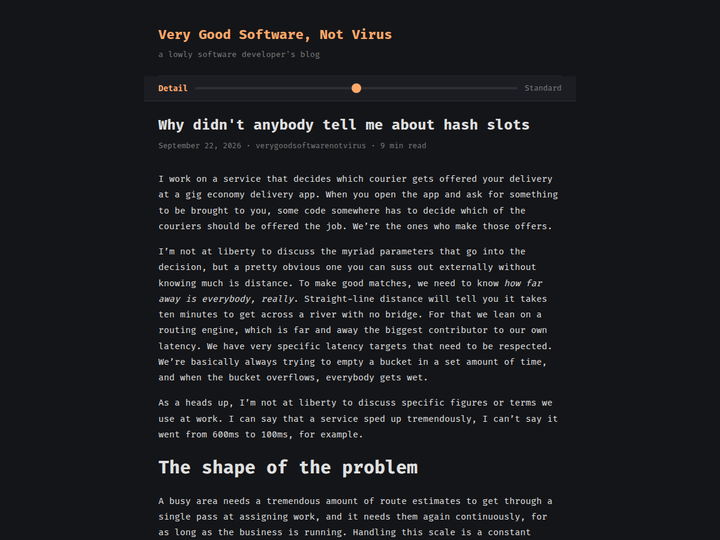
Why didn't anybody tell me about Redis hash slots?47blog.verygoodsoftwarenotvirus.dev原文 ↗
blog.verygoodsoftwarenotvirus.dev
文章通过实例解释 Redis Cluster 如何用 hash slot 把 key 映射到节点,以及客户端为何必须理解槽位迁移和路由。它补上了从单机 Redis 到集群部署之间常被忽略的心智模型,重点在分片机制而非命令清单。
–
The current balance of power in open models48interconnects.ai原文 ↗
interconnects.ai
Nathan Lambert 以国会证词梳理开放模型生态:文中称中国模型在 Hugging Face 下载总量领先美国约 32 亿对 16 亿,OpenRouter 使用份额超过 80%,AI 论文提及率约 38% 对美国 28%。他估计开放权重距闭源前沿约 2-5 个月,并指出开放能力扩张同时放大网络安全治理与跨境依赖问题。
–
GitHub 热门 · GitHub Trending
7 项 · GitHub 热门TencentCloud/Octop49github.com原文 ↗
github.com
Octop 用单进程把 Web、CLI、IM、cron 和 ACP 统一到 HarnessProcessor,支持多用户 JWT、16 种 MBTI persona、RAG、浏览器/终端自动化及 Codex/Claude Code 委派。SQLite 默认、PostgreSQL 可选,数据和 memory 留在 `~/.octop/`,定位是家庭与小团队的自托管 agent 控制面。
–
Tencent/BrowserSkill50github.com原文 ↗
github.com
BrowserSkill 让 agent 借用 Chrome/Edge 已登录状态,在独立窗口读写网页并记录请求、响应、console 与性能证据。它支持远程浏览器和 profile 绑定,但明确共享登录权限而非安全沙箱;调试记录默认 30 天、50 条/50MiB 上限,安全边界写进产品而不是留给使用者猜测。
–
hydra-db/hydradb51github.com原文 ↗
github.com
HydraDB 把图数据、WAL 和不可变遍历索引放在 S3 兼容对象存储,graph-node 与 graph-indexer 分离扩展;查询固定 SlateDB snapshot,并用 WAL overlay 补齐落后索引。它通过 Bolt 5.x、OpenCypher 和 GraphBLAS 兼顾既有 Neo4j 客户端与图原生执行。
–
huggingface/tokenizers52github.com原文 ↗
github.com
tokenizers 1.0.0.rc.0 以 Rust 核心、Python/Node 绑定和 325KB 压缩体积为卖点,并把训练、序列化和推理拆成独立 crate。bitcannon 将 Unicode 分类编译成 bitstream 标签,所有向量 kernel 都有标量 oracle,因而硬件差异影响速度而不改变 token 结果。
–
superdesigndev/treg53github.com原文 ↗
github.com
Treg 聚合 60+ provider 的 3,000+ 工具 endpoint,用一个 token 搜索、查看价格和调用;团队自己的 key、CLI、OAuth 与 SKILL.md 也能注册,凭据始终服务端注入。HTTP 402 返回余额和预估成本,配合审计日志和组织角色,体现的是工具供应链治理而非简单 MCP 代理。
–
dream-num/univer54github.com原文 ↗
github.com
Univer 用 Canvas、公式引擎、插件和 Facade API 提供可嵌入的表格/文档/演示 SDK,并可在 Node headless 运行,适合 agent 直接处理工作簿。Preset Mode 降低启动成本,Plugin Mode 保留细粒度加载;实时协作、导入导出等能力被明确划入 Pro,开源边界清楚。
–
google/ax55github.com原文 ↗
github.com
AX 以 `Task`、`Workspace`、`Gateway`、`Model` manifest 声明 agent 沙箱、预热仓库/MCP、网络白名单和模型凭据,控制面运行在 Kubernetes 上。`ax suspend/resume` 可 checkpoint,`ax ssh` 可进入运行中任务;项目同时警告规范尚未稳定,目标规模与当前协议成熟度之间存在明显工程风险。
–
引用来源 · References
55 条 · 引用- 1 AutoGym: Blueprint-First Generation of Verifiable Agent Gyms. arXiv:2609.22592https://arxiv.org/abs/2609.22592 ↩ 回到正文 · back to text
- 2 AgentRouter: Heterogeneous Model Routing for Cost-Optimal Multi-Step Agentic Workflows. arXiv:2609.22951https://arxiv.org/abs/2609.22951 ↩ 回到正文 · back to text
- 3 Jev-Mem: System-One-Controlled Agentic Memory for Efficient AI Agents. arXiv:2609.23986https://arxiv.org/abs/2609.23986 ↩ 回到正文 · back to text
- 4 Toollery: Scaling LLM Agents to Thousands of Skills and Tools. arXiv:2609.22218https://arxiv.org/abs/2609.22218 ↩ 回到正文 · back to text
- 5 AgentRunhttps://github.com/Parcha-ai/agentrun ↩ 回到正文 · back to text
- 6 Agreement Overstates Evidence: Error Dependence in LLM Judge Consensus. arXiv:2609.22512https://arxiv.org/abs/2609.22512 ↩ 回到正文 · back to text
- 7 MAWILE: Multi-Axis Workbench for Inspecting LLM Evaluators. arXiv:2609.22599https://arxiv.org/abs/2609.22599 ↩ 回到正文 · back to text
- 8 LazyAgent: Demand-Driven Materialization and Physical Optimization of Agentic Programs. arXiv:2609.23058https://arxiv.org/abs/2609.23058 ↩ 回到正文 · back to text
- 9 CraftBench-UE: Deterministic Evaluation for Coding Agents in Unreal Engine. arXiv:2609.23142https://arxiv.org/abs/2609.23142 ↩ 回到正文 · back to text
- 10 Do Not Trust the Benchmark: Limitations of General LLM Rankings and a Case for Task-Specific Evaluation. arXiv:2609.23201https://arxiv.org/abs/2609.23201 ↩ 回到正文 · back to text
- 11 Total Cost of Agency: Exact Attribution of Memory Injection Cost in Multi-Agent LLM Workflows. arXiv:2609.23790https://arxiv.org/abs/2609.23790 ↩ 回到正文 · back to text
- 12 WorkWorlds: An Infrastructure for Evaluating AI Agents on Workplace Tasks. arXiv:2609.23806https://arxiv.org/abs/2609.23806 ↩ 回到正文 · back to text
- 13 EDGEGEN: Improving Tool-Calling Agents Beyond Happy Paths with Synthetic Edge Case Generation. arXiv:2609.24115https://arxiv.org/abs/2609.24115 ↩ 回到正文 · back to text
- 14 Self-Healing Harness for Runtime Oversight of Agent Self-Modification. arXiv:2609.24130https://arxiv.org/abs/2609.24130 ↩ 回到正文 · back to text
- 15 When and How Should an Agent Clarify? CIGAsk: Teaching LLMs to Clarify via Counterfactual Information Gain. arXiv:2609.24290https://arxiv.org/abs/2609.24290 ↩ 回到正文 · back to text
- 16 MM-ContextFold: Context Folding for Multimodal Agentic Retrieval. arXiv:2609.23121https://arxiv.org/abs/2609.23121 ↩ 回到正文 · back to text
- 17 Lifeboathttps://github.com/IterateAI/lifeboat-releases ↩ 回到正文 · back to text
- 18 rubric-attesthttps://github.com/0xsims/rubric-attest ↩ 回到正文 · back to text
- 19 Jotterhttps://github.com/nfishel48/Jotter ↩ 回到正文 · back to text
- 20 Reflexhttps://github.com/lateos-ai/reflex ↩ 回到正文 · back to text
- 21 Psychosis Guardhttps://github.com/nwjang/psychosis-guard ↩ 回到正文 · back to text
- 22 Oxhttps://openox.ai/ ↩ 回到正文 · back to text
- 23 Sanemarkhttps://github.com/nkitsaini/sanemark ↩ 回到正文 · back to text
- 24 Tendernesshttps://github.com/paperchase-labs/tenderness ↩ 回到正文 · back to text
- 25 PCBClawhttps://github.com/liseman/pcbclaw ↩ 回到正文 · back to text
- 26 Axhttps://useax.dev/ ↩ 回到正文 · back to text
- 27 Karada.aihttps://karada.ai ↩ 回到正文 · back to text
- 28 Claude discovers a novel enzyme system with CRISPR-like repeatshttps://www.anthropic.com/news/claude-discovers-novel-enzyme-system ↩ 回到正文 · back to text
- 29 Gemini 3.8 text-to-speechhttps://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-8-text-to-speech/ ↩ 回到正文 · back to text
- 30 GPT-6 Astra has gained the ability to drive a carhttps://drivingbench.com/ ↩ 回到正文 · back to text
- 31 Strands Harnesshttps://strandsagents.com/blog/introducing-strands-harness/ ↩ 回到正文 · back to text
- 32 Stripe's Knowledge AI Platformhttps://stripe.dev/blog/meet-stripes-knowledge-ai-platform ↩ 回到正文 · back to text
- 33 Offloaded inference for real-world physical AI roboticshttps://www.microsoft.com/en-us/research/blog/offloaded-inference-for-real-world-physical-ai-robotics/ ↩ 回到正文 · back to text
- 34 Ringg’s AI agents resolve up to 65% of customer calls with OpenAIhttps://openai.com/index/ringg ↩ 回到正文 · back to text
- 35 Harvey turns legal context into stronger drafts with GPT-6 Astrahttps://openai.com/index/harvey-from-context-to-confidence-with-astra ↩ 回到正文 · back to text
- 36 Airbnb widens access to GPT-6 Astra and OpenAI frontier modelshttps://openai.com/index/airbnb-gpt-6-astra ↩ 回到正文 · back to text
- 37 How invideo improves color grading 3x with GPT-6 Astrahttps://openai.com/index/invideo-builds-with-gpt-6-astra ↩ 回到正文 · back to text
- 38 Gemini 3.8 TTS Playgroundhttps://simonwillison.net/2026/Sep/23/gemini-tts-playground/ ↩ 回到正文 · back to text
- 39 Shadow roots, explained with live exampleshttps://simonwillison.net/2026/Sep/23/shadow-roots/ ↩ 回到正文 · back to text
- 40 Claude Opus 5.5, GPT-6 Sol, GPT-6 Luna, and a new price warhttps://simonwillison.net/2026/Sep/22/opus-and-sol-and-luna/ ↩ 回到正文 · back to text
- 41 llm 0.36https://simonwillison.net/2026/Sep/22/llm/ ↩ 回到正文 · back to text
- 42 llm-anthropic 0.29https://simonwillison.net/2026/Sep/22/llm-anthropic/ ↩ 回到正文 · back to text
- 43 Why Omarchy Existshttps://mikael.pika.page/posts/why-omarchy-exists ↩ 回到正文 · back to text
- 44 Jev in 25 Lines of Pythonhttps://www.nobodywho.ai/posts/jev-in-25-lines/ ↩ 回到正文 · back to text
- 45 SAML: A fractal of bad designhttps://blog.trailofbits.com/2026/09/21/saml-a-fractal-of-bad-design/ ↩ 回到正文 · back to text
- 46 Tokens Too Cheap to Meterhttps://jyn.dev/tokens-too-cheap-to-meter/ ↩ 回到正文 · back to text
- 47 Why didn't anybody tell me about Redis hash slots?https://blog.verygoodsoftwarenotvirus.dev/posts/2026/09/23/why-didnt-anybody-tell-me-about-hash-slots/ ↩ 回到正文 · back to text
- 48 The current balance of power in open modelshttps://www.interconnects.ai/p/the-current-balance-of-power-in-open ↩ 回到正文 · back to text
- 49 TencentCloud/Octophttps://github.com/TencentCloud/Octop ↩ 回到正文 · back to text
- 50 Tencent/BrowserSkillhttps://github.com/Tencent/BrowserSkill ↩ 回到正文 · back to text
- 51 hydra-db/hydradbhttps://github.com/hydra-db/hydradb ↩ 回到正文 · back to text
- 52 huggingface/tokenizershttps://github.com/huggingface/tokenizers ↩ 回到正文 · back to text
- 53 superdesigndev/treghttps://github.com/superdesigndev/treg ↩ 回到正文 · back to text
- 54 dream-num/univerhttps://github.com/dream-num/univer ↩ 回到正文 · back to text
- 55 google/axhttps://github.com/google/ax ↩ 回到正文 · back to text